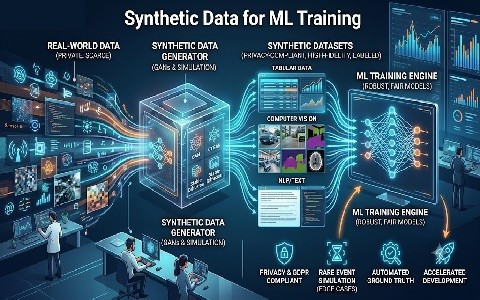
Vyom Data Sciences delivers privacy-compliant, ultra-realistic synthetic datasets designed to accelerate machine learning model development. By leveraging advanced generative AI, diffusion models, and simulation engines, we generate high-fidelity tabular, vision, and text data that mirrors real-world statistical distributions without privacy risks, annotation bottlenecks, or bias constraints.
What We Do
✔ Privacy-by-Design Datasets: Fully anonymized, regulation-compliant (GDPR/HIPAA) synthetic data for finance, healthcare, and sensitive enterprise applications.✔ Edge-Case & Rare-Event Simulation: Custom synthetic pipelines to train AI on hard-to-capture anomalies, rare defects, and stress scenarios.
✔ Automated Ground Truth & Labeling: Instant, error-free pixel-level segmentation, 3D bounding boxes, and structured annotations generated alongside dataset creation.
✔ Model Fine-Tuning & Distillation: High-quality instruction-response datasets to domain-adapt large language models (LLMs) safely and cost-effectively.
Core Value Proposition
We solve the #1 bottleneck in enterprise AI-data scarcity and regulatory risk. Our enterprise-grade synthetic data platform cuts data collection and labeling timelines by up to 80%, eliminates compliance friction, and improves model robustness across edge cases.At, Vyom Data Sciences, we help our clients, build high performance teams, across their organization. Check our website for full details or drop us a query.